Data Engineer vs. Analytics Engineer: Hire for the Right Outcome
Quick Summary: A data engineer builds and maintains reliable systems for collecting, storing, and processing data, while an analytics engineer develops tested, documented data models for analysis. Hire according to where the problem lies: data delivery, business logic, or both, with responsibilities scoped to your team’s needs.
Faster pipelines won’t resolve dashboards that use different revenue definitions. A data engineer can improve ingestion and monitoring, but sales and finance may still calculate revenue differently. Before hiring someone, the manager needs to find out why the numbers disagree. Otherwise, the new employee could do everything they were hired to do and still leave the original problem unresolved.
A data engineer vs. analytics engineer comparison often starts with tools and job titles. Those details matter, but it’s easier to choose the right person once the hiring team understands what’s going wrong. Define the failure first and name the role second.
Data Engineer vs. Analytics Engineer: Key Differences
A job description that lists Python, SQL, Snowflake, Airflow, dbt, and BigQuery tells candidates what they’ll be working with. It still leaves an important question unanswered: what does the company need them to fix? Several of those tools appear in both roles, so the list won’t settle the hiring decision.
The comparison below is a starting point. Where the responsibilities fall will depend on who’s already doing the work and where the team needs help.
Typical responsibilities overlap. Candidate evidence is an editorial recommendation. Use this in place of the article’s existing comparison table.
Sources: IBM: Data engineering · dbt Labs: Analytics engineering
Find Out Where the Problem Starts
When dashboards disagree, check what’s behind the numbers before deciding who to hire. Missing records or different refresh times can produce discrepancies even when the calculations match. Different filters or business definitions can produce them even when the underlying data is complete.
Data Isn’t Arriving Reliably
If data arrives late, requires manual uploads, or keeps getting lost between systems, data engineering is likely the priority. The work may involve connecting sources, automating ingestion, or fixing processing bottlenecks.
Pipeline failures frequently reach analysts before they reach the engineering team. When that happens, the team also needs better monitoring and a clearer process for responding to failures.
The job description should explain which sources cause trouble, who’s waiting for the data, and when they need it. That gives recruiters something useful to ask about and helps candidates understand whether they’ve handled similar work.
Rising warehouse and compute bills deserve a closer look, too. The cause could be an infrastructure decision or an inefficient transformation query, so a bigger bill doesn’t automatically mean the company needs a data engineer. Find out what’s driving the spending before making someone responsible for cutting it.
Data Exists, but People Don’t Trust It
When analysts keep cleaning the same datasets or rebuilding the same queries, analytics engineering may be the more pressing need. The same is true when nobody can explain how a warehouse model works or which reports depend on it. The data is there, but using it still requires too much checking and cleanup.
Customer retention is a good place to see how definitions can get tangled. Counting repeat purchases answers a different question from counting contract renewals. An active account may mean something else again.
Before anyone standardizes those calculations, the departments involved need to agree on the question they’re trying to answer. They don’t necessarily need one measure for every purpose.
An analytics engineer can help work through those requirements and build reusable models around the agreed definitions. They’ll test the logic, document how the models should be used, and update the code when requirements change. The business owners still need to approve what the metrics mean; the engineer can’t make that decision for them.
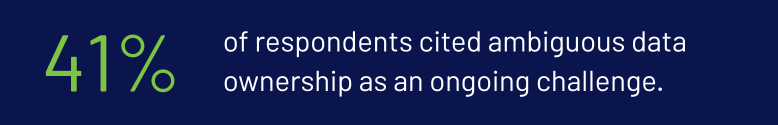
Unclear ownership is a recurring problem. In dbt Labs’ 2026 survey of 363 data practitioners and leaders, 41% cited ambiguous data ownership, and poor data quality remained the most frequently reported obstacle. A new hire needs to know who can approve a definition or resolve a disagreement, especially when several departments are involved.
Both Problems Need Attention
Unstable pipelines and inconsistent business logic often reinforce each other. Late or incomplete data forces analysts to create workarounds. Those workarounds generate more definitions and one-off models. When a number looks wrong, teams struggle to determine whether the cause sits in the source, pipeline, transformation, or report.
If there’s substantial work on both sides, two specialists may be the better fit. When the budget allows only one hire, decide what has to work first and what can wait.
Someone with experience across both roles can cover a blended position, provided the workload is realistic. A professional services team may also help complete a defined project while the company builds its internal team.
The job description should identify the first outcome the employee must improve, along with the responsibilities that can wait. Also agree on who investigates when something breaks and how they’ll hand the issue over if the cause lies elsewhere.
Decide What Should Be Better in Six Months
Candidates should be able to read the job description and understand what they’re being brought in to do. They’ll also need room to decide how to do it once they’ve seen the systems and talked with the people using them.
Describe What’s Failing
“Improve data quality” doesn’t give a candidate much to work with. Explain which datasets or reports cause problems, how often it happens, and what people can’t do as a result. Include what the team has already checked so the new hire doesn’t have to start that investigation over.
Identify Who Depends on the Work
Who will this person spend time working with? Infrastructure work often brings them alongside platform teams, architects, security leaders, and application developers. Work on metrics and business definitions usually means regular conversations with analysts and the departments using those numbers.
Both roles need someone who can explain a problem clearly and keep the right people informed. The hiring brief should name the people who approve changes and those who need to hear when something goes wrong.
Agree on What Must Improve
Choose measures that show whether the original problem is getting better. For data delivery, that may mean meeting agreed arrival times or reducing pipeline failures. For analytics engineering, it may mean getting priority metrics approved and tested, or reducing the time analysts spend cleaning up common datasets.
Before setting a six-month target, check where things stand today and what support the employee will have. They can’t improve a system they can’t access or settle a business definition nobody will approve. Make those dependencies clear so candidates can judge whether the assignment is realistic.
Recommended measures derived from the article and technical sources. Set targets from the employer’s baseline, workload, and available support. These are not published six-month benchmarks.
Sources: IBM: Data engineering · dbt: Source freshness · dbt: Data tests · dbt Labs: Analytics engineering
Ask What Candidates Have Actually Solved
Experience with the same platforms can help someone get started faster, especially in a complex environment. Ask what they’ve done with those tools, though, and how closely that work resembles the assignment at hand.
A data engineering candidate should be able to explain how they tracked down recurring pipeline failures or handled sources that were difficult to integrate. With analytics engineering candidates, explore how they built and tested reusable models, managed changes, and helped business teams use the results.
Find out what the candidate personally did and how the team knew it had worked.
Then bring the discussion back to the problem described in the hiring brief. Ask how they’d investigate it, what they’d check first, and how they’d keep affected teams informed. When revenue figures conflict, their approach should account for incomplete data, reporting logic, and different definitions before they recommend a fix.
Pay attention to what candidates ask before suggesting a solution. Someone who’s done similar work should be able to explain what they’d need to know and where they’d need help or approval. That conversation tells the hiring team more than a list of familiar tools.
Hire for the Work Your Team Needs
The hiring decision gets easier when the team can explain what’s going wrong and what the new person will be responsible for fixing. Candidates can then talk about the work they’ve actually done, and managers can judge how well that experience fits.
GDH’s IT staffing expertise includes data engineering and analytics, supported by industry knowledge that helps explain why the work matters to the business. If the team is still unsure which role it needs, contact GDH to talk through the responsibilities and the experience to look for.
Frequently Asked Questions
Can one person cover both roles?
Yes, especially on a smaller team, as long as the workload fits one person and they have experience across both areas. Make clear what comes first and where they’ll have support. A job description that includes both roles’ responsibilities needs realistic limits.
Which role should an early data team hire first?
If the team can’t collect and deliver the data it needs, data engineering generally comes first. If ingestion works but the models and business logic need attention, analytics engineering may be the better starting point. Check what managed ingestion tools already cover before adding responsibilities to the role.
How should employers evaluate candidates from a different technology environment?
Ask whether they’ve solved a similar problem at a comparable scale, then talk through what they’d need to learn. Their explanation of how they’d adapt can help the hiring team judge both their experience and the support they’d need. Someone who has handled similar work on another platform can usually get up to speed with good documentation and a clear onboarding plan.